
DeepSeek can make AI more capable at a given price without making every AI stock a better investment. For Nvidia and memory-stock investors, the crucial questions are how cheaper useful output changes paid usage, customer orders, supplier margins and the valuation already in the share price.
This guide builds on our HBM, DRAM and NAND investing breakdown. It adapts the investment questions in our Japanese DeepSeek note into an English explanation with original worked examples. Information checked October 18, 2026; model capabilities, tariffs and disclosures can change.
Watch DeepSeek vs Nvidia: Are AI Stocks in Danger? on YouTube
What changed in DeepSeek-V4.1-Flash-1017?
DeepSeek announced its October 17 update to V4.1-Flash, including its web and app, while leaving API pricing unchanged. This is an improvement claim at an existing tariff, rather than a fresh October 17 price cut. Source: DeepSeek update log.
The developer’s evaluation reports Terminal-Bench 4.0 moving from 31.2 to 42.3 and DeepSWE v1.1 from 74.2 to 77.0. The differences are 11.1 and 2.8 points. They are separate tests, rather than interchangeable measures of general productivity. Source: official model card.
Did DeepSeek beat GPT and Claude?
Identify the exact comparison release and evaluation setup. The card lists GPT-5.6 Sol and Opus 5; results vary by benchmark. That table cannot establish a winner over every competing release or task. It uses specified harnesses, including Claude Code for Terminal-Bench 4.0 and Mini-SWE-V2 for DeepSWE. Treat the scores as developer-reported evidence, then test your workload.
A business adoption test should include the cost of retries, human review, failed jobs, integration and latency. A lower token tariff with a poor success rate may be a worse economic choice than a higher tariff with reliable output. Conversely, a cheaper model that meets the task’s quality threshold can put pressure on premium pricing without leading every benchmark.
API pricing is not the model’s total cost
DeepSeek lists different tariffs for input cache hits, misses and output, with peak and off-peak conditions. These are customer charges, not a disclosure of training expenditure or a provider’s margin. Source: official pricing and billing conditions.
For an investor, keep four quantities separate: price per billed unit, paid usage, variable cost per unit and fixed costs. A token tariff also differs from the cost of one successfully completed task. We do not assign an old DeepSeek model’s reported training expense to this update, estimate its undisclosed profits, or infer a chip model from an API price.
The revenue trap: half the price requires more than twice the usage
The following is a fictional service business, not DeepSeek, Nvidia or any listed company. Assume one period, all service units sold, a single price, linear variable costs and fixed costs of $20. The example omits taxes, interest, working capital, capital expenditure and the timing of cash flows.
| Metric | Initial case | Changed case |
|---|---|---|
| Service units | 100 | 200 |
| Price per unit | $1.00 | $0.50 |
| Revenue | $100 | $100 |
| Variable cost per unit | $0.40 | $0.30 |
| Total variable cost | $40 | $60 |
| Fixed costs | $20 | $20 |
| Operating profit | $40 | $20 |
Revenue is price × units. Halving the price while doubling the units leaves revenue unchanged. Operating profit is revenue − total variable cost − fixed costs. Here, improved variable cost per unit does not prevent operating profit from falling 50%, because the lower selling price squeezes contribution per unit from $0.60 to $0.20.
How much usage restores the original profit?
At a $0.50 selling price and $0.30 variable cost, each extra service unit contributes $0.20 before fixed costs. Restoring the initial $40 profit requires ($40 + $20) ÷ $0.20 = 300 units.
| Changed-price scenario | Revenue | Operating profit |
|---|---|---|
| 200 units | $100 | $20 |
| 250 units | $125 | $30 |
| 300 units | $150 | $40 |
At 250 units, revenue exceeds the initial $100, yet operating profit remains below the initial $40. At 300 units, profit merely returns to its starting level. These are sensitivity calculations with chosen assumptions, not a forecast or a claim that a price cut actually occurred on October 17. A different cost curve changes the answer.
Does Jevons paradox guarantee more Nvidia demand?
No. Efficiency can expand usage enough to increase total resource consumption; the rebound idea is often called the Jevons paradox. Invesco discussed it in its March 2025 DeepSeek analysis. That is an investment interpretation of the earlier episode, not proof of the current update’s outcome. Source: Invesco, In Focus: AI after DeepSeek, page 6.
Separate three hurdles. First, useful paid workloads must grow. Second, that growth must translate into the specific resource a supplier sells. Third, the supplier must retain enough price and margin to earn an attractive return on its investment. A larger industry can fail any individual company’s shareholder-return test.
Do not treat a named paradox as a demand forecast. Lower costs may unlock valuable tasks, but adoption also depends on reliability, organizational change, budgets, network and power limits. Some usage may move to competing hardware or different deployments. The practical question is how much new business offsets how much resource saved per task.
HBM efficiency: define the memory component first
The September V4.1-Flash paper reports global KV-cache bytes per token in HBM at roughly one-quarter of the V4-Flash baseline. KV cache stores intermediate information used in processing context. That is a specific component metric, not total HBM, GPU purchases or electricity. Source: DeepSeek technical paper, abstract.
The following illustrative multipliers assume that component’s per-token capacity ratio is 0.25 and everything else is held constant. The workload is the number of tokens held concurrently, not annual API requests. The workload multipliers are invented and have no assigned probabilities.
| Concurrent stored tokens | Capacity per token | Total capacity for this component |
|---|---|---|
| 2× starting workload | 0.25× baseline | 0.50× baseline |
| 4× starting workload | 0.25× baseline | 1.00× baseline |
| 8× starting workload | 0.25× baseline | 2.00× baseline |
The arithmetic is capacity per token × concurrent token count. At four times the concurrent tokens, this component’s total capacity returns to the starting level. At eight times, it doubles. Other memory components, model weights, bandwidth, deployment and utilization remain outside this calculation. None of these rows predicts total HBM demand.
Follow the business exposure: Nvidia, HBM and NAND are different bets
| Exposure | Decision to investigate | Evidence to look for |
|---|---|---|
| Accelerator suppliers, including Nvidia | Do workloads and utilization change hardware orders? | Customer commitments, hardware mix and realized selling prices |
| HBM suppliers | Does bandwidth or capacity become the binding constraint? | Customer qualification, orders, pricing and capacity additions |
| NAND / SSD businesses | Which persistent storage workloads increase? | Storage architecture, product mix and sustainable margins |
| AI application businesses | Do lower model bills improve customer economics? | Paid retention, cost per successful task and competitive pricing |
This table is our analytical checklist, not a ranking or a forecast about named companies. Use current company disclosures to fill it in. Episode four explains why HBM, DRAM and NAND exposures differ; our full memory-industry map provides broader company context.
What do the distillation allegations establish?
Distillation can be a legitimate method of training on a stronger model’s outputs. Unauthorized collection is a separate allegation. Anthropic’s February report attributed a campaign to DeepSeek; its September report alleged additional collection and selective relaying of customer requests during July. These are the reporting company’s findings, not our independent audit or a determination of this update’s training provenance. February report; September report, GTG-16001 section.
Neither public weights nor an API format establishes the complete training history. We do not quantify how much any alleged collection contributed to the October model. A customer should evaluate deployment, contractual access, reliability and data handling on their own facts. An investor should distinguish operational or access risk from a proven prediction of lost revenue.
Growing earnings can still produce a falling stock price
Consider a second fictional example. A stock has $5 EPS and a P/E of 30, so the illustrative price is $150. EPS rises to $6 but the multiple falls to 20, leaving a $120 price.
| Scenario | EPS | P/E | Illustrative price |
|---|---|---|---|
| Starting assumptions | $5 | 30× | $150 |
| Higher earnings, lower multiple | $6 | 20× | $120 |
EPS is up 20%; the price is down 20%. This is arithmetic sensitivity, not a price target, probability or valuation of Nvidia or any other company. Dividends, trading costs and taxes are excluded. The example demonstrates why a correct view about growing AI adoption can still disappoint if the price paid assumes more.
Before buying the DeepSeek dip: an investor checklist
- Identify the new fact. Is it a benchmark result, a tariff change, a customer order, or only a market narrative?
- Write the economic bridge. How does that fact change paid demand, costs, investment and cash generation for this particular company?
- State what the price needs. Which margin, growth rate and valuation assumption must hold?
- Check correlated exposure. Do several holdings depend on the same customer spending cycle?
- Write a disconfirming condition. What evidence would make you reduce confidence rather than automatically add?
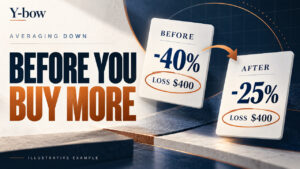
Our first episode shows why averaging down does not instantly remove a dollar loss. The second compares DCA with a lump-sum investment. The third tests the cost of waiting to buy a dip. Together they distinguish purchase rules from the quality and price of the business being purchased.
Frequently asked questions
Does cheaper DeepSeek AI make Nvidia chips unnecessary?
The evidence above does not establish that. Better efficiency can reduce resource use for a fixed workload, while more usage, different hardware choices and deployment constraints can change aggregate orders. Examine the customer’s actual purchasing decision.
Did the October 17 update reduce API prices?
DeepSeek’s announcement says pricing was unchanged. A model that completes tasks more efficiently can reduce some task bills without changing the published tariff.
Does a one-quarter global KV cache mean HBM demand falls 75%?
No. It concerns one component per token relative to a particular baseline. Concurrent workloads, other memory uses and bandwidth requirements also matter.
Is this a buy or sell recommendation?
No. The guide explains how to test a narrative. The calculations are hypothetical, not personalized investment advice, company forecasts or guaranteed returns.
Original analysis and diagrams with AI-assisted narration and conceptual artwork. Vendor evaluations are attributed, calculations independently checked. No affiliate offer is inserted in this article. Information and prices can change; consult the linked primary documents and company disclosures before acting.

Comments